Ranking one page for one keyword stopped working as a strategy years ago. What works now is structure: pillars, clusters and spokes, wired together so Google's crawlers and AI retrieval systems can both see everything you know about a topic.
Key takeaways
- Topical authority is how well you cover a whole subject, judged by semantic breadth, entity depth and internal links that point both ways. It has nothing to do with keyword density on a single page.
- A solid structure has three tiers: broad Pillar Pages, intent-specific Cluster Pages and granular Spokes, all linked in a closed loop.
- Internal links are not decoration. They tell crawlers where a topic starts and ends, and they tell RAG systems which chunks belong together.
- The structure that wins classic rankings also decides whether an LLM can pull your content out cleanly enough to cite it. One build, two audiences.
- The most common failure is not thin content. It's links leaking between clusters and orphaned spokes, and neither shows up in a rankings report.
On this page
Why Topical Authority Matters Now
Topical authority is how well a site covers a defined subject area. It's judged on semantic breadth, entity depth and internal links that reinforce each other, not on keyword density in one page.
Google announced its topic authority system in May 2023 and described it as a way to find expert sources for queries in specialized areas like health, politics or finance. The signals it named were how notable a source is for a topic or location, whether other publishers cite its original reporting, and its track record of quality work. Google's Search Liaison later said this wasn't a new launch. The system had been running for years, so the announcement was disclosure, not deployment.
That context matters. Google described topic authority for news surfaces, so calling it a confirmed sitewide ranking factor overstates the evidence. What the announcement does confirm is the principle underneath: credibility is judged at the source-and-topic level, not purely page by page, and that principle shapes a lot of search today.
The mechanical shift is entity reconciliation. Instead of matching a query's characters to a document's characters, modern retrieval resolves both into entities, which are concepts with defined relationships in a knowledge graph, and checks whether your site covers that entity's neighborhood in real depth.
LLM-based answer engines work on a similar logic when they pick sources. Given a multi-step prompt, a retrieval system doesn't grab one page at random. It builds context from sources that look authoritative across the whole topic, because a site that covers a subject fully gives it more retrievable chunks that back each other up than a site with one isolated post.
The 3-Tier Structure: Pillars, Clusters and Spokes
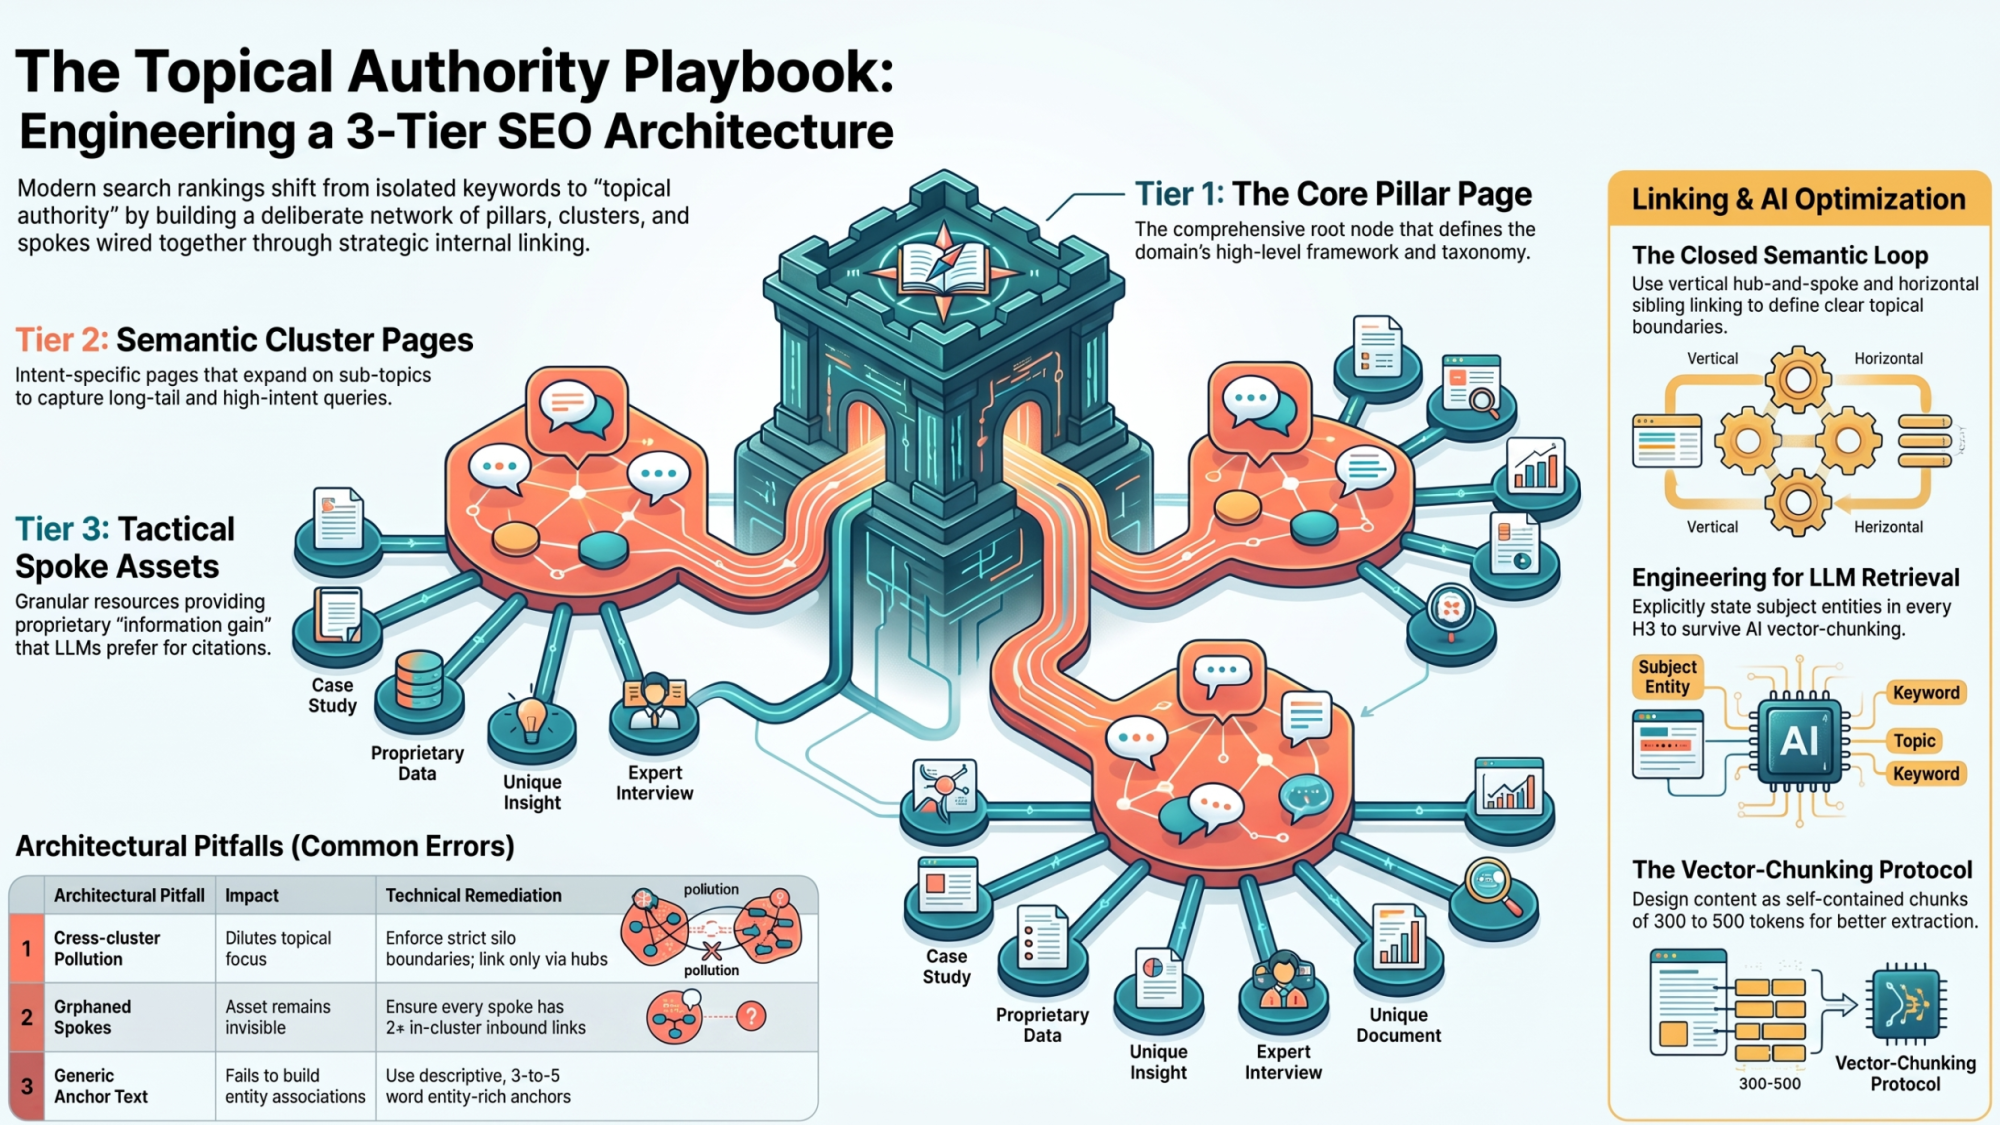
A solid content structure has three tiers: broad canonical Pillar Pages, intent-specific Cluster Pages and granular Spoke Assets, linked in a closed loop.
Tier 1: The Core Pillar Page (Entity Root)
A Pillar Page is the root of a topic. It targets the broad head term and sets the boundaries for everything under it. It earns its place by defining the domain, not by covering every detail.
What belongs on a pillar: high-level definitions, the framework that organizes the topic, a map of the sub-areas, and enough summary of each one to orient the reader. What goes to clusters: step-by-step implementation, tool-specific instructions, edge cases, and anything that would make the pillar too long to navigate. A pillar that tries to hold everything ends up as a page nobody finishes and a crawler can't summarize.
Tier 2: Cluster Pages (Middle-of-Funnel Depth)
Cluster Pages take one sub-topic from the pillar and cover it in full. They go after the long-tail, high-intent queries the pillar deliberately leaves unanswered.
Cannibalization is a real risk, but a manageable one. A cluster page only competes with its parent when both target the same intent. If the pillar answers "what is X" and the cluster answers "how to implement X on Shopify," they serve different intents and support each other. My test before publishing any cluster: could the pillar fully satisfy this page's target query? If yes, it's a section of the pillar, not a separate URL.
Tier 3: Spokes (Bottom-of-Funnel Detail)
Spoke Assets are small, single-purpose resources: SOPs, code snippets, calculation formulas and case teardowns that fully answer one specific operational question.
Spokes matter a lot for AI citation because that's where proprietary information gain piles up. A generic overview can be pieced together from a dozen existing sources. A documented teardown of one specific failure, with the real numbers, can't. My own JavaScript SEO checklist covering rendering and hydration failures is a spoke of exactly this kind: narrow, operational, and full of detail you won't find in aggregate anywhere else.
3 Ways to Link Your Pages Internally
Internal linking topology decides how crawlers and RAG systems map relationships between pages, how equity flows, and where a topic's boundaries sit across your site.
1. The Strict Hub-and-Spoke Model (Vertical Isolation)
Hub-and-spoke linking means every cluster page links up to its pillar and the pillar links down to every cluster page. That forms a complete vertical loop inside one topic.
The discipline that makes this work is the silo rule: unrelated clusters don't cross-link. When a page about schema implementation casually links to a page about paid media, it tells a crawler those topics are related, and that blurs the boundary the silo is there to draw. Equity should move between unrelated topics only through the parent hub, never sideways. Holding to this consistently is part of the technical SEO architecture work that most content teams skip.
2. Bidirectional Sibling Linking (Horizontal Topical Weaving)
Sibling linking connects cluster pages in the same silo directly, adding horizontal context that a strict vertical hierarchy can't express.
A cluster page on schema implementation should link naturally to a sibling page on schema validator tools, because a reader who finishes the first genuinely needs the second. Two rules keep this from going bad: only link where the connection is real, not to hit a quota, and vary the anchor text between sibling pairs. If every page links to the same sibling with the identical phrase, the anchor signal flattens into noise instead of sharpening the entity association.
3. Breadcrumbs
Breadcrumbs give crawlers a clear map of your site taxonomy as an explicit path, such as Home > Category > Pillar > Cluster.
Breadcrumbs matter more than their visual prominence suggests because they remove ambiguity. Contextual links express relationships probabilistically; a breadcrumb states the hierarchy outright. Implement them with BreadcrumbList JSON-LD so the hierarchy is machine-readable and not inferred from CSS.
Making Clusters Easy for LLMs to Use
Optimizing clusters for LLM retrieval means structuring pages into self-contained pieces of text that answer engines can pull out, verify and cite without losing context.
How to Write for Chunking
Retrieval systems slice documents into chunks, commonly 300 to 500 tokens, and embed each chunk on its own before storing it. A chunk that only makes sense next to the paragraph before it loses its meaning the moment it's retrieved alone.
The rule I follow: every H3 section states its subject entity in the opening sentence instead of leaning on a pronoun that points backward. "It requires three inputs" is useless when retrieved in isolation. "Entity gap analysis requires three inputs" survives the slice. It's the same principle behind zero-click answers versus deep long-form content, applied at the paragraph level instead of the page level.
Adding Information Gain
Information gain measures how much a document adds beyond what a user has already seen. It's what separates a source worth citing from one that's merely summarizable.
Google's Information Gain patent (US20200349181A1) describes scoring candidate documents by how much extra information they contain compared with documents the user already viewed. Most articles only cite the application number, so here's the lineage: that 2020 publication was granted as US11354342B2 in 2022, and a later continuation, US12013887B2, was granted in 2024 and extends the concept explicitly to automated assistants. Google has never confirmed how directly any of these operate in live ranking, but the 2024 continuation's focus on assistants makes the principle especially relevant to AI answer engines.
Three methods reliably produce real gain: original benchmark data from your own work, branded framework terms that give models a specific label to attribute, and documented failure points, the things that went wrong in practice, which scrapers and synthesis engines have no source for.
Nested Schema @graph Linking
Nested JSON-LD ties a cluster page to its parent pillar through explicit relationship properties, turning an implied hierarchy into a declared one.
Use isPartOf on the cluster pointing to the pillar, hasPart on the pillar pointing to the clusters, and about plus mentions pointing to authoritative Wikidata or Wikipedia entity URLs. Put it all in a single @graph instead of several disconnected script blocks, following the W3C JSON-LD 1.1 specification. Property definitions for isPartOf and the rest live on schema.org. Check them there directly instead of copying from a blog post, since property expectations change between versions.
If deploying nested entity graphs across a whole cluster sounds like more schema work than your team has time for, my Generative Engine Optimization (GEO) & AI Citation OS has these as pre-validated copy-paste templates, plus a 25-point readiness audit.
How to Build Your First Authority Cluster
Launching an authority cluster takes four phases in order: entity gap analysis, content topology mapping, staged publishing, and closed-loop internal link enforcement.
Phase 1: Find Your Entities and Sub-Topics
Entity gap analysis finds every sub-node a topic needs before you draft a single word, using entity relationships instead of keyword volume to decide what's in.
Mine the Google Knowledge Graph Search API for entities related to your root term, read the "People also ask" and related-search carousels as a map of the question space, and check competitor sites for sub-topics they cover and you don't. One caveat before you build tooling around it: Google now labels that API as migrating to Cloud Enterprise Knowledge Graph and warns it isn't suitable as a production-critical service, so treat it as a research input, not a dependency. To traverse actual entity relationships instead of looking up single entities, Google's own documentation recommends Wikidata data dumps.
Volume tools will tell you a sub-topic gets 40 searches a month and suggest skipping it. Entity logic says that if the sub-topic is structurally part of the domain, leaving it out is a hole in your coverage, whatever its volume.
Phase 2: Map Your Content and Anchors
Content mapping gives you a sheet that assigns every planned URL its primary entity anchor and sibling link pairings before you start drafting.
Do this upfront because ad-hoc linking while writing produces a messy graph nobody can audit later. Build a simple table with columns for URL, tier, parent pillar, target entity, inbound anchor text and required sibling links. Writers then add links as specified instead of improvising, and you can check the graph is closed before publishing instead of finding orphans months later.
Phase 3: Staged vs. Batch Publishing
Batch deployment publishes a whole cluster at once; staged publishing releases pages over weeks or months. Batch is generally faster at establishing topical signal, but you need the full content investment before any of it goes live.
Batch publishing lets a crawler meet the entire link graph at once, so the topical relationship is visible immediately instead of being assembled piece by piece. Staged publishing risks a long window where clusters are partly indexed, spokes are orphaned, and the pillar points to pages that don't exist yet. If you have to stage, finish each silo before starting the next, instead of publishing one page from every silo.
Phase 4: Check the Links After Publishing
Closed-loop enforcement means checking, after publication, that every planned link exists and every page has its required inbound connections.
Most teams skip this phase, and it's where architecture quietly fails. Crawl the site after publishing and check three things: every spoke has at least two in-cluster inbound links, every cluster links up to its pillar, and no link crosses a silo boundary. A plan is not a graph. Only the crawl shows what you actually built.
Common Mistakes That Kill Topical Authority
| Architectural Pitfall | Impact on Google | Impact on Answer Engines | Technical Remediation |
|---|---|---|---|
| Cross-cluster link pollution | Dilutes topical focus across unrelated categories | Produces mixed-context or inaccurate citations | Enforce strict silo boundaries; link across topics only via parent hubs |
| Keyword cannibalization | Multiple pages compete for identical intent; rank volatility | Model extracts conflicting definitions across URLs | Consolidate duplicate intent; enforce canonical 301s |
| Orphaned spokes | Crawler fails to discover deep pages; equity stalls | Zero vector retrieval; asset remains invisible | Ensure every spoke has at least 2 in-cluster inbound links |
| Generic anchor text | Passes PageRank without semantic context signals | Fails to build entity associations in embeddings | Use descriptive, 3-to-5 word entity-rich anchors |
| JavaScript-only internal links | Links not in raw HTML may go undiscovered | Invisible to non-rendering AI crawlers entirely | Render all internal links as native <a href> in initial HTML |
The failure mode nobody catches in a rankings report. Every pitfall above is invisible if you only track keyword positions. Orphaned spokes and silo pollution don't show up as a ranking drop. They show up as pages that never gain traction in the first place, which is much harder to notice.
Frequently Asked Questions
How many cluster pages does a pillar need before it establishes topical authority?
There is no fixed threshold, and any specific number you see quoted is invented. What matters is whether the cluster covers the sub-topics a reasonably informed person would expect the domain to contain. Five clusters that completely cover a narrow topic outperform twenty that partially cover a broad one.
Should cluster pages ever link to clusters in a different silo?
As a default rule, no. Route cross-topic connections through the parent pillars instead. The exception is a genuinely substantive connection a reader would actively need, in which case one deliberate link is fine. The problem is habitual cross-linking, not a single justified one.
Does this architecture work for e-commerce category structures, not just blog content?
Yes, and the tiers map cleanly: category pages act as pillars, sub-category and buying-guide pages as clusters, individual product and comparison pages as spokes. The silo discipline matters more in e-commerce, since faceted navigation generates cross-links automatically unless controlled. See our e-commerce SEO services for how this plays out at catalog scale.
How long before a new cluster shows measurable results?
Indexation of a batch-published cluster typically happens within days to a few weeks depending on crawl frequency. Meaningful ranking and citation movement usually takes longer, commonly 3 to 6 months, because topical authority is assessed over time rather than at the moment of publication.
Can I retrofit this structure onto an existing site with years of unstructured content?
Yes, and it is usually more valuable than starting fresh, since you already have content with accumulated authority. Start with an audit that maps existing URLs to tiers, identifies cannibalization pairs for consolidation, and finds orphans. Most retrofits find that the pillar content already exists in fragments and needs consolidating rather than writing from scratch.
From Traffic Volume to Topic Ownership
How to Measure Cluster Performance
Measure cluster health in aggregate: combined organic impressions across the silo, how often your brand shows up in AI answers, and pipeline velocity, instead of individual keyword positions.
Tracking disconnected keyword rankings is misleading at this level. A cluster can gain authority while individual page rankings bounce around, and a page can rank well while contributing nothing to pipeline. Track three things instead: total impressions across all URLs in the silo, how often your brand appears in AI-generated answers for the topic, and how many qualified conversations come from cluster content.
Work With Me on Your Topical Authority
Moving from scattered keyword targeting to a topical authority network takes technical architecture, careful entity mapping and content built to hold up in search. Whether you're restructuring a large catalog or defending your brand against AI search, Digital Appears can help with technical SEO, Generative Engine Optimization and semantic architecture.
Not sure whether your existing content is a cluster or just a pile of posts?
I map your existing URLs to tiers, find cannibalization pairs and orphaned assets, and build the link graph your content should have had from the start.
Talk to Digital Appears about a topical architecture audit →Related reading